実行時間制限: 2 sec / メモリ制限: 1024 MiB
配点 : 100 点
問題文
4 種類の牡蠣 1,2,3,4 があります。 このうちちょうど 1 種類の牡蠣については、食べるとお腹を壊してしまいます。 それ以外の牡蠣については、食べてもお腹を壊しません。
高橋君が牡蠣 1,2 を食べ、青木君が牡蠣 1,3 を食べました。
二人がこれによってお腹を壊したかどうかの情報が二つの文字列 S_1,S_2 によって与えられます。
具体的には、S_1= sick であるとき高橋君がお腹を壊したことを、S_1= fine であるとき高橋君がお腹を壊さなかったことを表します。
同様に、S_2= sick であるとき青木君がお腹を壊したことを、S_2= fine であるとき青木君がお腹を壊さなかったことを表します。
与えられた情報をもとに、どの種類の牡蠣を食べるとお腹を壊すか判定してください。
制約
- S_1, S_2 はそれぞれ
sickまたはfine
入力
入力は以下の形式で標準入力から与えられる。
S_1 S_2
出力
食べるとお腹を壊す牡蠣の種類の番号を出力せよ。
入力例 1
sick fine
出力例 1
2
牡蠣 1,2 を食べた高橋君はお腹を壊し、牡蠣 1,3 を食べた青木君はお腹を壊さなかったので、牡蠣 2 を食べるとお腹を壊すことがわかります。
入力例 2
fine fine
出力例 2
4
牡蠣 1,2 を食べた高橋君も牡蠣 1,3 を食べた青木君もお腹を壊さなかったので、残る牡蠣 4 を食べるとお腹を壊すことがわかります。
Score : 100 points
Problem Statement
There are four types of oysters, labeled 1, 2, 3, and 4. Exactly one of these types causes stomach trouble if eaten. The other types do not cause stomach trouble when eaten.
Takahashi ate oysters 1 and 2, and Aoki ate oysters 1 and 3. The information on whether each person got sick is given as two strings S_1 and S_2. Specifically, S_1 = sick means Takahashi got sick, and S_1 = fine means Takahashi did not get sick. Likewise, S_2 = sick means Aoki got sick, and S_2 = fine means Aoki did not get sick.
Based on the given information, find which type of oyster causes stomach trouble.
Constraints
- Each of S_1 and S_2 is
sickorfine.
Input
The input is given from Standard Input in the following format:
S_1 S_2
Output
Print the label of the oyster that causes stomach trouble if eaten.
Sample Input 1
sick fine
Sample Output 1
2
Takahashi (who ate oysters 1 and 2) got sick, and Aoki (who ate oysters 1 and 3) did not get sick, so it can be concluded that oyster 2 causes stomach trouble.
Sample Input 2
fine fine
Sample Output 2
4
Neither Takahashi (who ate oysters 1 and 2) nor Aoki (who ate oysters 1 and 3) got sick, so it can be concluded that oyster 4 causes stomach trouble.
実行時間制限: 2 sec / メモリ制限: 1024 MiB
配点 : 100 点
問題文
末尾が er または ist であるような文字列 S が与えられます。
S の末尾が er である場合は er を、 ist である場合は ist を出力してください。
制約
- 2 \le |S| \le 20
- S は英小文字のみからなる。
- S の末尾は
erまたはistである。
入力
入力は以下の形式で標準入力から与えられる。
S
出力
答えを出力せよ。
入力例 1
atcoder
出力例 1
er
S="atcoder" の末尾は er です。
入力例 2
tourist
出力例 2
ist
入力例 3
er
出力例 3
er
Score : 100 points
Problem Statement
You are given a string S ending with er or ist.
If S ends with er, print er; if it ends with ist, print ist.
Constraints
- 2 \le |S| \le 20
- S consists of lowercase English letters.
- S ends with
erorist.
Input
Input is given from Standard Input in the following format:
S
Output
Print the answer.
Sample Input 1
atcoder
Sample Output 1
er
S="atcoder" ends with er.
Sample Input 2
tourist
Sample Output 2
ist
Sample Input 3
er
Sample Output 3
er
実行時間制限: 2 sec / メモリ制限: 1024 MiB
配点 : 200 点
問題文
英小文字のみからなる 2 つの文字列 S, T が与えられます。 S が T の接頭辞かどうかを判定してください。
接頭辞とは
長さ N の文字列 T_1T_2\ldots T_N の接頭辞とは、 0 \leq i \leq N を満たすある整数 i によって、T の先頭 i 文字目までの文字列 T_1T_2\ldots T_i として表される文字列です。例えば、T = abc のとき、T の接頭辞は、空文字列、a 、ab 、abc の 4 つです。制約
- S と T はそれぞれ英小文字のみからなる長さが 1 以上 100 以下の文字列
入力
入力は以下の形式で標準入力から与えられる。
S
T
出力
S が T の接頭辞である場合は Yes を、そうでない場合は No を出力せよ。
ジャッジは英小文字と英大文字を厳密に区別することに注意せよ。
入力例 1
atco
atcoder
出力例 1
Yes
atco は atcoder の接頭辞です。よって、Yes を出力します。
入力例 2
code
atcoder
出力例 2
No
code は atcoder の接頭辞ではありません。よって、No を出力します。
入力例 3
abc
abc
出力例 3
Yes
文字列全体もその文字列の接頭辞であることに注意してください。
入力例 4
aaaa
aa
出力例 4
No
Score : 200 points
Problem Statement
You are given two strings S and T consisting of lowercase English letters. Determine if S is a prefix of T.
What is a prefix?
A prefix of a string T_1T_2\ldots T_N of length N is a string expressed as the first i characters of T, T_1T_2\ldots T_i, where i is an integer such that 0 \leq i \leq N. For example, when T = abc, there are four prefixes of T: an empty string, a, ab, and abc.Constraints
- S and T are strings of lengths between 1 and 100 (inclusive) consisting of lowercase English letters.
Input
Input is given from Standard Input in the following format:
S
T
Output
Print Yes if S is a prefix of T; print No otherwise.
Note that the judge is case-sensitive.
Sample Input 1
atco
atcoder
Sample Output 1
Yes
atco is a prefix of atcoder. Thus, Yes should be printed.
Sample Input 2
code
atcoder
Sample Output 2
No
code is not a prefix of atcoder. Thus, No should be printed.
Sample Input 3
abc
abc
Sample Output 3
Yes
Note that a string is also a prefix of itself.
Sample Input 4
aaaa
aa
Sample Output 4
No
実行時間制限: 2 sec / メモリ制限: 1024 MiB
配点 : 200 点
問題文
キーエンスでは良いことも悪いこともありのままに報告するという文化があります。
そこで、報告内容が元の文章のありのままであるかを確認したいです。
英小文字のみからなる文字列 S, T が与えられます。
S と T が等しいならば 0 を、そうでないならば異なっている文字のうち先頭のものが何文字目かを出力してください。
ただし、S,T の一方にのみ i 文字目が存在するときも、i 文字目は異なっているとみなすものとします。
より厳密には、S と T が等しくないならば次の条件のうちいずれかをみたす最小の整数 i を出力してください。
- 1\leq i\leq |S| かつ 1\leq i\leq |T| かつ S_i\neq T_i
- |S|< i\leq |T|
- |T|< i\leq |S|
ただし、|S|,|T| でそれぞれ S,T の長さを、S_i,T_i でそれぞれ S,T の i 文字目を表します。
制約
- S,T は英小文字のみからなる長さ 1 以上 100 以下の文字列
入力
入力は以下の形式で標準入力から与えられる。
S
T
出力
S と T が等しいならば 0 を、そうでないならば異なっている文字のうち先頭のものが何文字目かを出力せよ。
入力例 1
abcde
abedc
出力例 1
3
S=abcde, T=abedc です。
S と T は 1,2 文字目は等しく、3 文字目が異なるため、 3 を出力します。
入力例 2
abcde
abcdefg
出力例 2
6
S=abcde, T=abcdefg です。
S と T は 5 文字目まで等しく、T にのみ 6 文字目が存在するため、6 を出力します。
入力例 3
keyence
keyence
出力例 3
0
S と T は等しいため、 0 を出力します。
Score : 200 points
Problem Statement
KEYENCE has a culture of reporting things as they are, whether good or bad.
So we want to check whether the reported content is exactly the same as the original text.
You are given two strings S and T, consisting of lowercase English letters.
If S and T are equal, print 0; otherwise, print the position of the first character where they differ.
Here, if the i-th character exists in only one of S and T, consider that the i-th characters are different.
More precisely, if S and T are not equal, print the smallest integer i satisfying one of the following conditions:
- 1\leq i\leq |S|, 1\leq i\leq |T|, and S_i\neq T_i.
- |S| < i \leq |T|.
- |T| < i \leq |S|.
Here, |S| and |T| denote the lengths of S and T, respectively, and S_i and T_i denote the i-th characters of S and T, respectively.
Constraints
- S and T are strings of length between 1 and 100, inclusive, consisting of lowercase English letters.
Input
The input is given from Standard Input in the following format:
S
T
Output
If S and T are equal, print 0; otherwise, print the position of the first character where they differ.
Sample Input 1
abcde
abedc
Sample Output 1
3
We have S= abcde and T= abedc.
S and T have the same first and second characters, but differ at the third character, so print 3.
Sample Input 2
abcde
abcdefg
Sample Output 2
6
We have S= abcde and T= abcdefg.
S and T are equal up to the fifth character, but only T has a sixth character, so print 6.
Sample Input 3
keyence
keyence
Sample Output 3
0
S and T are equal, so print 0.
実行時間制限: 2 sec / メモリ制限: 1024 MiB
配点 : 300 点
問題文
N 行 N 列のマス目があります。 上から i 行目、左から j 列目のマスを (i,j) と表記します。 はじめ、マス目の上には何も置かれていません。
今から M 回の操作を行います。 i 回目 (1\leq i\leq M) の操作は以下の通りです。
- マス (R_i,C_i) を左上とする 2 \times 2 の領域を占めるブロックを、既に置かれている他のブロックと位置が重ならない場合、またその場合に限り、マス目の上に置く。 より厳密には、マス集合 S=\lbrace (R_i,C_i),(R_i+1,C_i),(R_i,C_i+1),(R_i+1,C_i+1)\rbrace に対し、既にマス目の上に置かれているブロックであって S に含まれるいずれかのマスを占めるものが存在するならば何も行わず、 存在しないならば S に含まれる 4 マス全体を占めるブロックを置く。
全ての操作を行った後、マス目の上に何個のブロックが置かれているか求めてください。
制約
- 2\leq N \leq 10^9
- 1\leq M \leq 2\times 10^5
- 1\leq R_i,C_i \leq N-1
- 入力は全て整数
入力
入力は以下の形式で標準入力から与えられる。
N M
R_1 C_1
R_2 C_2
\vdots
R_M C_M
出力
答えを出力せよ。
入力例 1
4 3
1 1
2 2
2 3
出力例 1
2
以下の図は操作のようすを示したものであり、黒く塗られた領域がブロックを、赤枠で囲まれた領域が次にブロックを置きたい場所を表しています。
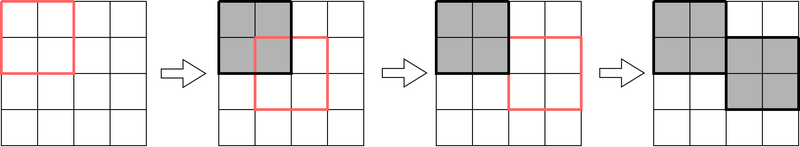
- 1 回目の操作:マス (1,1) を左上とする 2 \times 2 の領域には何も置かれていないため、そこにブロックを置きます。
- 2 回目の操作:マス (2,2) を左上とする 2 \times 2 の領域のうち、マス (2,2) 上に既に他のブロックが存在するため、何も行いません。
- 3 回目の操作:マス (2,3) を左上とする 2 \times 2 の領域には何も置かれていないため、そこにブロックを置きます。
よって、全ての操作を行った後、マス目の上に 2 個のブロックが置かれています。
入力例 2
1000000000 4
1 1
1 101
101 1
101 101
出力例 2
4
全ての操作においてブロックを置くことができます。
入力例 3
8 10
6 5
7 3
6 7
3 4
4 2
3 7
1 3
7 4
6 1
6 1
出力例 3
8
(R_i,C_i)=(R_j,C_j) を満たす i,j\ (i\neq j) が存在することもあります。
Score : 300 points
Problem Statement
There is a grid with N rows and N columns. Let (i,j) denote the cell at the i-th row from the top and j-th column from the left. Initially, nothing is placed on the grid.
You will now perform M operations. The i-th operation (1\leq i\leq M) is as follows:
- Place a block that occupies a 2 \times 2 region with cell (R_i,C_i) as the top-left corner on the grid if and only if its position does not overlap with any other blocks already placed. More precisely, for the set of cells S=\lbrace (R_i,C_i),(R_i+1,C_i),(R_i,C_i+1),(R_i+1,C_i+1)\rbrace, if there exists a block already placed on the grid that occupies any cell in S, do nothing; otherwise, place a block that occupies all four cells in S.
After performing all operations, find how many blocks are placed on the grid.
Constraints
- 2\leq N \leq 10^9
- 1\leq M \leq 2\times 10^5
- 1\leq R_i,C_i \leq N-1
- All input values are integers.
Input
The input is given from Standard Input in the following format:
N M
R_1 C_1
R_2 C_2
\vdots
R_M C_M
Output
Print the answer.
Sample Input 1
4 3
1 1
2 2
2 3
Sample Output 1
2
The following diagram shows the operations, where black-filled regions represent blocks and red-framed regions represent where the next block is to be placed.
- Operation 1: Nothing is placed in the 2 \times 2 region with cell (1,1) as the top-left corner, so place a block there.
- Operation 2: Among the 2 \times 2 region with cell (2,2) as the top-left corner, there is already another block on cell (2,2), so do nothing.
- Operation 3: Nothing is placed in the 2 \times 2 region with cell (2,3) as the top-left corner, so place a block there.
Thus, after performing all operations, two blocks are placed on the grid.
Sample Input 2
1000000000 4
1 1
1 101
101 1
101 101
Sample Output 2
4
Blocks can be placed in all operations.
Sample Input 3
8 10
6 5
7 3
6 7
3 4
4 2
3 7
1 3
7 4
6 1
6 1
Sample Output 3
8
There may exist i,j\ (i\neq j) such that (R_i,C_i)=(R_j,C_j).