Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 100 点
問題文
4 種類の牡蠣 1,2,3,4 があります。 このうちちょうど 1 種類の牡蠣については、食べるとお腹を壊してしまいます。 それ以外の牡蠣については、食べてもお腹を壊しません。
高橋君が牡蠣 1,2 を食べ、青木君が牡蠣 1,3 を食べました。
二人がこれによってお腹を壊したかどうかの情報が二つの文字列 S_1,S_2 によって与えられます。
具体的には、S_1= sick であるとき高橋君がお腹を壊したことを、S_1= fine であるとき高橋君がお腹を壊さなかったことを表します。
同様に、S_2= sick であるとき青木君がお腹を壊したことを、S_2= fine であるとき青木君がお腹を壊さなかったことを表します。
与えられた情報をもとに、どの種類の牡蠣を食べるとお腹を壊すか判定してください。
制約
- S_1, S_2 はそれぞれ
sickまたはfine
入力
入力は以下の形式で標準入力から与えられる。
S_1 S_2
出力
食べるとお腹を壊す牡蠣の種類の番号を出力せよ。
入力例 1
sick fine
出力例 1
2
牡蠣 1,2 を食べた高橋君はお腹を壊し、牡蠣 1,3 を食べた青木君はお腹を壊さなかったので、牡蠣 2 を食べるとお腹を壊すことがわかります。
入力例 2
fine fine
出力例 2
4
牡蠣 1,2 を食べた高橋君も牡蠣 1,3 を食べた青木君もお腹を壊さなかったので、残る牡蠣 4 を食べるとお腹を壊すことがわかります。
Score : 100 points
Problem Statement
There are four types of oysters, labeled 1, 2, 3, and 4. Exactly one of these types causes stomach trouble if eaten. The other types do not cause stomach trouble when eaten.
Takahashi ate oysters 1 and 2, and Aoki ate oysters 1 and 3. The information on whether each person got sick is given as two strings S_1 and S_2. Specifically, S_1 = sick means Takahashi got sick, and S_1 = fine means Takahashi did not get sick. Likewise, S_2 = sick means Aoki got sick, and S_2 = fine means Aoki did not get sick.
Based on the given information, find which type of oyster causes stomach trouble.
Constraints
- Each of S_1 and S_2 is
sickorfine.
Input
The input is given from Standard Input in the following format:
S_1 S_2
Output
Print the label of the oyster that causes stomach trouble if eaten.
Sample Input 1
sick fine
Sample Output 1
2
Takahashi (who ate oysters 1 and 2) got sick, and Aoki (who ate oysters 1 and 3) did not get sick, so it can be concluded that oyster 2 causes stomach trouble.
Sample Input 2
fine fine
Sample Output 2
4
Neither Takahashi (who ate oysters 1 and 2) nor Aoki (who ate oysters 1 and 3) got sick, so it can be concluded that oyster 4 causes stomach trouble.
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 100 点
問題文
末尾が er または ist であるような文字列 S が与えられます。
S の末尾が er である場合は er を、 ist である場合は ist を出力してください。
制約
- 2 \le |S| \le 20
- S は英小文字のみからなる。
- S の末尾は
erまたはistである。
入力
入力は以下の形式で標準入力から与えられる。
S
出力
答えを出力せよ。
入力例 1
atcoder
出力例 1
er
S="atcoder" の末尾は er です。
入力例 2
tourist
出力例 2
ist
入力例 3
er
出力例 3
er
Score : 100 points
Problem Statement
You are given a string S ending with er or ist.
If S ends with er, print er; if it ends with ist, print ist.
Constraints
- 2 \le |S| \le 20
- S consists of lowercase English letters.
- S ends with
erorist.
Input
Input is given from Standard Input in the following format:
S
Output
Print the answer.
Sample Input 1
atcoder
Sample Output 1
er
S="atcoder" ends with er.
Sample Input 2
tourist
Sample Output 2
ist
Sample Input 3
er
Sample Output 3
er
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 200 点
問題文
英小文字のみからなる 2 つの文字列 S, T が与えられます。 S が T の接頭辞かどうかを判定してください。
接頭辞とは
長さ N の文字列 T_1T_2\ldots T_N の接頭辞とは、 0 \leq i \leq N を満たすある整数 i によって、T の先頭 i 文字目までの文字列 T_1T_2\ldots T_i として表される文字列です。例えば、T = abc のとき、T の接頭辞は、空文字列、a 、ab 、abc の 4 つです。制約
- S と T はそれぞれ英小文字のみからなる長さが 1 以上 100 以下の文字列
入力
入力は以下の形式で標準入力から与えられる。
S
T
出力
S が T の接頭辞である場合は Yes を、そうでない場合は No を出力せよ。
ジャッジは英小文字と英大文字を厳密に区別することに注意せよ。
入力例 1
atco
atcoder
出力例 1
Yes
atco は atcoder の接頭辞です。よって、Yes を出力します。
入力例 2
code
atcoder
出力例 2
No
code は atcoder の接頭辞ではありません。よって、No を出力します。
入力例 3
abc
abc
出力例 3
Yes
文字列全体もその文字列の接頭辞であることに注意してください。
入力例 4
aaaa
aa
出力例 4
No
Score : 200 points
Problem Statement
You are given two strings S and T consisting of lowercase English letters. Determine if S is a prefix of T.
What is a prefix?
A prefix of a string T_1T_2\ldots T_N of length N is a string expressed as the first i characters of T, T_1T_2\ldots T_i, where i is an integer such that 0 \leq i \leq N. For example, when T = abc, there are four prefixes of T: an empty string, a, ab, and abc.Constraints
- S and T are strings of lengths between 1 and 100 (inclusive) consisting of lowercase English letters.
Input
Input is given from Standard Input in the following format:
S
T
Output
Print Yes if S is a prefix of T; print No otherwise.
Note that the judge is case-sensitive.
Sample Input 1
atco
atcoder
Sample Output 1
Yes
atco is a prefix of atcoder. Thus, Yes should be printed.
Sample Input 2
code
atcoder
Sample Output 2
No
code is not a prefix of atcoder. Thus, No should be printed.
Sample Input 3
abc
abc
Sample Output 3
Yes
Note that a string is also a prefix of itself.
Sample Input 4
aaaa
aa
Sample Output 4
No
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 200 点
問題文
キーエンスでは良いことも悪いこともありのままに報告するという文化があります。
そこで、報告内容が元の文章のありのままであるかを確認したいです。
英小文字のみからなる文字列 S, T が与えられます。
S と T が等しいならば 0 を、そうでないならば異なっている文字のうち先頭のものが何文字目かを出力してください。
ただし、S,T の一方にのみ i 文字目が存在するときも、i 文字目は異なっているとみなすものとします。
より厳密には、S と T が等しくないならば次の条件のうちいずれかをみたす最小の整数 i を出力してください。
- 1\leq i\leq |S| かつ 1\leq i\leq |T| かつ S_i\neq T_i
- |S|< i\leq |T|
- |T|< i\leq |S|
ただし、|S|,|T| でそれぞれ S,T の長さを、S_i,T_i でそれぞれ S,T の i 文字目を表します。
制約
- S,T は英小文字のみからなる長さ 1 以上 100 以下の文字列
入力
入力は以下の形式で標準入力から与えられる。
S
T
出力
S と T が等しいならば 0 を、そうでないならば異なっている文字のうち先頭のものが何文字目かを出力せよ。
入力例 1
abcde
abedc
出力例 1
3
S=abcde, T=abedc です。
S と T は 1,2 文字目は等しく、3 文字目が異なるため、 3 を出力します。
入力例 2
abcde
abcdefg
出力例 2
6
S=abcde, T=abcdefg です。
S と T は 5 文字目まで等しく、T にのみ 6 文字目が存在するため、6 を出力します。
入力例 3
keyence
keyence
出力例 3
0
S と T は等しいため、 0 を出力します。
Score : 200 points
Problem Statement
KEYENCE has a culture of reporting things as they are, whether good or bad.
So we want to check whether the reported content is exactly the same as the original text.
You are given two strings S and T, consisting of lowercase English letters.
If S and T are equal, print 0; otherwise, print the position of the first character where they differ.
Here, if the i-th character exists in only one of S and T, consider that the i-th characters are different.
More precisely, if S and T are not equal, print the smallest integer i satisfying one of the following conditions:
- 1\leq i\leq |S|, 1\leq i\leq |T|, and S_i\neq T_i.
- |S| < i \leq |T|.
- |T| < i \leq |S|.
Here, |S| and |T| denote the lengths of S and T, respectively, and S_i and T_i denote the i-th characters of S and T, respectively.
Constraints
- S and T are strings of length between 1 and 100, inclusive, consisting of lowercase English letters.
Input
The input is given from Standard Input in the following format:
S
T
Output
If S and T are equal, print 0; otherwise, print the position of the first character where they differ.
Sample Input 1
abcde
abedc
Sample Output 1
3
We have S= abcde and T= abedc.
S and T have the same first and second characters, but differ at the third character, so print 3.
Sample Input 2
abcde
abcdefg
Sample Output 2
6
We have S= abcde and T= abcdefg.
S and T are equal up to the fifth character, but only T has a sixth character, so print 6.
Sample Input 3
keyence
keyence
Sample Output 3
0
S and T are equal, so print 0.
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 300 点
問題文
N 行 N 列のマス目があります。 上から i 行目、左から j 列目のマスを (i,j) と表記します。 はじめ、マス目の上には何も置かれていません。
今から M 回の操作を行います。 i 回目 (1\leq i\leq M) の操作は以下の通りです。
- マス (R_i,C_i) を左上とする 2 \times 2 の領域を占めるブロックを、既に置かれている他のブロックと位置が重ならない場合、またその場合に限り、マス目の上に置く。 より厳密には、マス集合 S=\lbrace (R_i,C_i),(R_i+1,C_i),(R_i,C_i+1),(R_i+1,C_i+1)\rbrace に対し、既にマス目の上に置かれているブロックであって S に含まれるいずれかのマスを占めるものが存在するならば何も行わず、 存在しないならば S に含まれる 4 マス全体を占めるブロックを置く。
全ての操作を行った後、マス目の上に何個のブロックが置かれているか求めてください。
制約
- 2\leq N \leq 10^9
- 1\leq M \leq 2\times 10^5
- 1\leq R_i,C_i \leq N-1
- 入力は全て整数
入力
入力は以下の形式で標準入力から与えられる。
N M
R_1 C_1
R_2 C_2
\vdots
R_M C_M
出力
答えを出力せよ。
入力例 1
4 3
1 1
2 2
2 3
出力例 1
2
以下の図は操作のようすを示したものであり、黒く塗られた領域がブロックを、赤枠で囲まれた領域が次にブロックを置きたい場所を表しています。
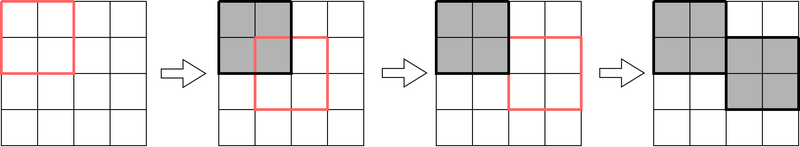
- 1 回目の操作:マス (1,1) を左上とする 2 \times 2 の領域には何も置かれていないため、そこにブロックを置きます。
- 2 回目の操作:マス (2,2) を左上とする 2 \times 2 の領域のうち、マス (2,2) 上に既に他のブロックが存在するため、何も行いません。
- 3 回目の操作:マス (2,3) を左上とする 2 \times 2 の領域には何も置かれていないため、そこにブロックを置きます。
よって、全ての操作を行った後、マス目の上に 2 個のブロックが置かれています。
入力例 2
1000000000 4
1 1
1 101
101 1
101 101
出力例 2
4
全ての操作においてブロックを置くことができます。
入力例 3
8 10
6 5
7 3
6 7
3 4
4 2
3 7
1 3
7 4
6 1
6 1
出力例 3
8
(R_i,C_i)=(R_j,C_j) を満たす i,j\ (i\neq j) が存在することもあります。
Score : 300 points
Problem Statement
There is a grid with N rows and N columns. Let (i,j) denote the cell at the i-th row from the top and j-th column from the left. Initially, nothing is placed on the grid.
You will now perform M operations. The i-th operation (1\leq i\leq M) is as follows:
- Place a block that occupies a 2 \times 2 region with cell (R_i,C_i) as the top-left corner on the grid if and only if its position does not overlap with any other blocks already placed. More precisely, for the set of cells S=\lbrace (R_i,C_i),(R_i+1,C_i),(R_i,C_i+1),(R_i+1,C_i+1)\rbrace, if there exists a block already placed on the grid that occupies any cell in S, do nothing; otherwise, place a block that occupies all four cells in S.
After performing all operations, find how many blocks are placed on the grid.
Constraints
- 2\leq N \leq 10^9
- 1\leq M \leq 2\times 10^5
- 1\leq R_i,C_i \leq N-1
- All input values are integers.
Input
The input is given from Standard Input in the following format:
N M
R_1 C_1
R_2 C_2
\vdots
R_M C_M
Output
Print the answer.
Sample Input 1
4 3
1 1
2 2
2 3
Sample Output 1
2
The following diagram shows the operations, where black-filled regions represent blocks and red-framed regions represent where the next block is to be placed.
- Operation 1: Nothing is placed in the 2 \times 2 region with cell (1,1) as the top-left corner, so place a block there.
- Operation 2: Among the 2 \times 2 region with cell (2,2) as the top-left corner, there is already another block on cell (2,2), so do nothing.
- Operation 3: Nothing is placed in the 2 \times 2 region with cell (2,3) as the top-left corner, so place a block there.
Thus, after performing all operations, two blocks are placed on the grid.
Sample Input 2
1000000000 4
1 1
1 101
101 1
101 101
Sample Output 2
4
Blocks can be placed in all operations.
Sample Input 3
8 10
6 5
7 3
6 7
3 4
4 2
3 7
1 3
7 4
6 1
6 1
Sample Output 3
8
There may exist i,j\ (i\neq j) such that (R_i,C_i)=(R_j,C_j).
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 300 点
問題文
N 頂点 M 辺の単純無向グラフが与えられます。頂点には 1, 2, \dots, N の番号が、辺には 1, 2, \dots, M の番号が付けられています。
辺 i \, (i = 1, 2, \dots, M) は頂点 u_i, v_i を結んでいます。
このグラフがパスグラフであるか判定してください。
単純無向グラフとは
単純無向グラフとは、自己ループや多重辺を含まず、辺に向きの無いグラフのことをいいます。
パスグラフとは
頂点に 1, 2, \dots, N の番号が付けられたN 頂点のグラフがパスグラフであるとは、(1, 2, \dots, N) を並べ変えて得られる数列 (v_1, v_2, \dots, v_N) であって、以下の条件を満たすものが存在することをいいます。
制約
- 2 \leq N \leq 2 \times 10^5
- 0 \leq M \leq 2 \times 10^5
- 1 \leq u_i, v_i \leq N \, (i = 1, 2, \dots, M)
- 入力される値は全て整数
- 入力で与えられるグラフは単純
入力
入力は以下の形式で標準入力から与えられる。
N M
u_1 v_1
u_2 v_2
\vdots
u_M v_M
出力
与えられたグラフがパスグラフなら Yes、そうでないなら No と出力せよ。
入力例 1
4 3
1 3
4 2
3 2
出力例 1
Yes
与えらえたグラフは下図のようであり、これはパスグラフです。

入力例 2
2 0
出力例 2
No
与えらえたグラフは下図のようであり、これはパスグラフではありません。

入力例 3
5 5
1 2
2 3
3 4
4 5
5 1
出力例 3
No
与えらえたグラフは下図のようであり、これはパスグラフではありません。

Score : 300 points
Problem Statement
You are given a simple undirected graph with N vertices and M edges. The vertices are numbered 1, 2, \dots, N, and the edges are numbered 1, 2, \dots, M.
Edge i \, (i = 1, 2, \dots, M) connects vertices u_i and v_i.
Determine if this graph is a path graph.
What is a simple undirected graph?
A simple undirected graph is a graph without self-loops or multiple edges whose edges do not have a direction.
What is a path graph?
A graph with N vertices numbered 1, 2, \dots, N is said to be a path graph if and only if there is a sequence (v_1, v_2, \dots, v_N) that is a permutation of (1, 2, \dots, N) and satisfies the following conditions:
Constraints
- 2 \leq N \leq 2 \times 10^5
- 0 \leq M \leq 2 \times 10^5
- 1 \leq u_i, v_i \leq N \, (i = 1, 2, \dots, M)
- All values in the input are integers.
- The graph given in the input is simple.
Input
The input is given from Standard Input in the following format:
N M
u_1 v_1
u_2 v_2
\vdots
u_M v_M
Output
Print Yes if the given graph is a path graph; print No otherwise.
Sample Input 1
4 3
1 3
4 2
3 2
Sample Output 1
Yes
Illustrated below is the given graph, which is a path graph.
Sample Input 2
2 0
Sample Output 2
No
Illustrated below is the given graph, which is not a path graph.
Sample Input 3
5 5
1 2
2 3
3 4
4 5
5 1
Sample Output 3
No
Illustrated below is the given graph, which is not a path graph.
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 400 点
問題文
すぬけ君は蛇を観察しており、どこからどこまでが頭・胴・尾なのかが気になっています。 すぬけ君は蛇を N 個のブロックに区切り、それぞれのブロックについて頭らしさ・胴らしさ・尾らしさを評価しました。 そして、らしさの合計が最大になる分け方を考えることにしました。
長さ N の整数列 A = (A_1, A_2, \ldots, A_N), B = (B_1, B_2, \ldots, B_N), C = (C_1, C_2, \ldots, C_N) が与えられます。
整数の組 (x, y) が 1 \leq x < y < N を満たすとき、\displaystyle\sum_{i = 1}^{x} A_i + \sum_{i = x + 1}^{y} B_i + \sum_{i = y + 1}^{N} C_i の値として取り得る最大値を求めてください。
制約
- 3 \leq N \leq 3 \times 10^5
- 1 \leq A_i, B_i, C_i \leq 10^6
- 入力される値はすべて整数
入力
入力は以下の形式で標準入力から与えられる。
N
A_1 A_2 \ldots A_N
B_1 B_2 \ldots B_N
C_1 C_2 \ldots C_N
出力
答えを出力せよ。
入力例 1
5
1 4 2 4 3
2 3 4 2 2
3 2 4 4 3
出力例 1
16
(x, y) = (2, 3) とすると \displaystyle\sum_{i = 1}^{x} A_i + \sum_{i = x + 1}^{y} B_i + \sum_{i = y + 1}^{N} C_i = 1 + 4 + 4 + 4 + 3 = 16 となります。
入力例 2
3
1 1 1
1 1 1
1 1 1
出力例 2
3
入力例 3
6
2 10 7 7 7 11
5 7 9 10 9 12
6 6 7 10 12 7
出力例 3
50
Score : 400 points
Problem Statement
Snuke is observing a snake and is curious about which parts are the head, body, and tail. He divided the snake into N blocks and evaluated the head-likeness, body-likeness, and tail-likeness of each block. Then, he decided to find the division that maximizes the sum of the likeness values.
You are given length-N integer sequences A = (A_1, A_2, \ldots, A_N), B = (B_1, B_2, \ldots, B_N), and C = (C_1, C_2, \ldots, C_N).
Find the maximum possible value of \displaystyle\sum_{i = 1}^{x} A_i + \sum_{i = x + 1}^{y} B_i + \sum_{i = y + 1}^{N} C_i for a pair of integers (x, y) satisfying 1 \leq x < y < N.
Constraints
- 3 \leq N \leq 3 \times 10^5
- 1 \leq A_i, B_i, C_i \leq 10^6
- All input values are integers.
Input
The input is given from Standard Input in the following format:
N
A_1 A_2 \ldots A_N
B_1 B_2 \ldots B_N
C_1 C_2 \ldots C_N
Output
Output the answer.
Sample Input 1
5
1 4 2 4 3
2 3 4 2 2
3 2 4 4 3
Sample Output 1
16
With (x, y) = (2, 3), we have \displaystyle\sum_{i = 1}^{x} A_i + \sum_{i = x + 1}^{y} B_i + \sum_{i = y + 1}^{N} C_i = 1 + 4 + 4 + 4 + 3 = 16.
Sample Input 2
3
1 1 1
1 1 1
1 1 1
Sample Output 2
3
Sample Input 3
6
2 10 7 7 7 11
5 7 9 10 9 12
6 6 7 10 12 7
Sample Output 3
50
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 500 点
問題文
長さ N の数列 A = (A_1, A_2, \dots, A_N) および整数 X, Y があります。 次の条件をすべて満たす整数の組 (L, R) の個数を求めてください。
- 1 \leq L \leq R \leq N
- A_L, A_{L+1}, \dots, A_R の最大値は X であり、最小値は Y である。
制約
- 1 \leq N \leq 2 \times 10^5
- 1 \leq A_i \leq 2 \times 10^5
- 1 \leq Y \leq X \leq 2 \times 10^5
- 入力される値はすべて整数である。
入力
入力は以下の形式で標準入力から与えられる。
N X Y
A_1 A_2 \dots A_N
出力
答えを出力せよ。
入力例 1
4 3 1
1 2 3 1
出力例 1
4
条件を満たすのは (L,R)=(1,3),(1,4),(2,4),(3,4) の 4 通りです。
入力例 2
5 2 1
1 3 2 4 1
出力例 2
0
条件を満たす (L,R) は存在しません。
入力例 3
5 1 1
1 1 1 1 1
出力例 3
15
X=Y である場合もあります。
入力例 4
10 8 1
2 7 1 8 2 8 1 8 2 8
出力例 4
36
Score : 500 points
Problem Statement
We have a number sequence A = (A_1, A_2, \dots, A_N) of length N and integers X and Y. Find the number of pairs of integers (L, R) satisfying all the conditions below.
- 1 \leq L \leq R \leq N
- The maximum value of A_L, A_{L+1}, \dots, A_R is X, and the minimum is Y.
Constraints
- 1 \leq N \leq 2 \times 10^5
- 1 \leq A_i \leq 2 \times 10^5
- 1 \leq Y \leq X \leq 2 \times 10^5
- All values in input are integers.
Input
Input is given from Standard Input in the following format:
N X Y
A_1 A_2 \dots A_N
Output
Print the answer.
Sample Input 1
4 3 1
1 2 3 1
Sample Output 1
4
4 pairs satisfy the conditions: (L,R)=(1,3),(1,4),(2,4),(3,4).
Sample Input 2
5 2 1
1 3 2 4 1
Sample Output 2
0
No pair (L,R) satisfies the condition.
Sample Input 3
5 1 1
1 1 1 1 1
Sample Output 3
15
It may hold that X=Y.
Sample Input 4
10 8 1
2 7 1 8 2 8 1 8 2 8
Sample Output 4
36
Time Limit: 2 sec / Memory Limit: 1024 MiB
配点 : 525 点
問題文
数列 A があります。 はじめ、A=(0) です。 (すなわち、A は 0 を唯一の要素として含む長さ 1 の数列です)。
クエリが Q 個与えられるので、順に処理してください。 i 番目 (1\leq i\leq Q) のクエリは以下のいずれかの形式です。
1 x:A の中で x が現れる場所の直後に i を挿入する。- 具体的には、現在の A の j 番目の要素を A_j、A の長さを n としたとき、A_p=x なる p に対して A を (A_1,\dots,A_p,i,A_{p+1},\dots,A_n) で更新する。 ここで、このクエリを処理する直前の時点で A には x が含まれていることが保証される。
2 x y:A の中で x と y の間にある要素の値の合計を出力し、それらの要素を全て削除する。- 具体的には、現在の A の j 番目の要素を A_j、A の長さを n としたとき、A_p=x,A_q=y なる p,q に対して、A_{\min(p,q)+1} + \dots + A_{\max(p,q)-1} を出力し、 A を (A_1,\dots,A_{\min(p,q)},A_{\max(p,q)},\dots,A_n) で更新する。 ここで、このクエリを処理する直前の時点で A には x および y が共に含まれていることが保証される。
なお、どのようなクエリの列に対しても、クエリを処理する過程で A の中に同じ値が複数回現れることはなく、ゆえに A の中である値が現れる場所は(存在するならば)一意であることに注意してください。
制約
- 1\leq Q \leq 5\times 10^5
- i 番目のクエリについて、
- 1 種類目のクエリのとき:
- 0\leq x < i
- クエリを処理する直前の時点で A には x が含まれる
- 2 種類目のクエリのとき:
- 0\leq x < y < i
- クエリを処理する直前の時点で A には x,y が共に含まれる
- 1 種類目のクエリのとき:
- 入力は全て整数
入力
入力は以下の形式で標準入力から与えられる。
Q
\text{query}_{1}
\text{query}_{2}
\vdots
\text{query}_{Q}
ここで \text{query}_{i} は i 番目のクエリを表し、以下のいずれかの形式で与えられる。
1 x
2 x y
出力
2 種類目のクエリの個数を q 個として、q 行出力せよ。 i 行目には、2 種類目のクエリのうち i 番目のものにおいて出力すべき値を出力せよ。
入力例 1
6
1 0
1 1
1 0
2 2 3
1 2
2 0 5
出力例 1
1
5
最初、A=(0) です。
- 1 番目のクエリ:0 の直後に 1 を挿入します。A=(0,1) になります。
- 2 番目のクエリ:1 の直後に 2 を挿入します。A=(0,1,2) になります。
- 3 番目のクエリ:0 の直後に 3 を挿入します。A=(0,3,1,2) になります。
- 4 番目のクエリ:2 と 3 の間にある要素、すなわち 1 を削除し、削除した値の合計である 1 を出力します。A=(0,3,2) になります。
- 5 番目のクエリ:2 の直後に 5 を挿入します。A=(0,3,2,5) になります。
- 6 番目のクエリ:0 と 5 の間にある要素、すなわち 3,2 を削除し、削除した値の合計である 5 を出力します。A=(0,5) になります。
入力例 2
2
1 0
2 0 1
出力例 2
0
2 番目のクエリでは 0 と 1 の間にある要素を全て削除しますが、実際にはそのような要素は一つも存在せず、要素の削除も行われないため、出力する値は 0 になります。
入力例 3
10
1 0
1 1
2 0 2
2 0 2
1 0
1 5
2 0 5
2 2 6
1 6
1 9
出力例 3
1
0
0
0
Score : 525 points
Problem Statement
There is a sequence A. Initially, A=(0). (That is, A is a sequence of length 1 containing 0 as its only element).
You are given Q queries to process in order. The i-th query (1\leq i\leq Q) has one of the following forms:
1 x: Insert i immediately after the location where x appears in A. Specifically, let A_j be the j-th element of the current A and n be the length of A. For p such that A_p=x, update A to (A_1,\dots,A_p,i,A_{p+1},\dots,A_n). It is guaranteed that A contains x immediately before processing this query.2 x y: Remove all elements between x and y in A, and output the sum of the values of the removed elements. Specifically, let A_j be the j-th element of the current A and n be the length of A. For p and q such that A_p=x and A_q=y, output A_{\min(p,q)+1} + \dots + A_{\max(p,q)-1} and update A to (A_1,\dots,A_{\min(p,q)},A_{\max(p,q)},\dots,A_n). It is guaranteed that A contains both x and y immediately before processing this query.
Note that for any sequence of queries, the same value never appears multiple times in A during the process of handling queries, and thus the position where a value appears in A is unique (if it exists).
Constraints
- 1\leq Q \leq 5\times 10^5
- For the i-th query:
- If it is a type 1 query:
- 0\leq x < i
- A contains x immediately before processing the query.
- If it is a type 2 query:
- 0\leq x < y < i
- A contains both x and y immediately before processing the query.
- If it is a type 1 query:
- All input values are integers.
Input
The input is given from Standard Input in the following format:
Q
\text{query}_{1}
\text{query}_{2}
\vdots
\text{query}_{Q}
Here, \text{query}_{i} represents the i-th query and is given in one of the following forms:
1 x
2 x y
Output
Let q be the number of type 2 queries. Output q lines. The i-th line should contain the value to be output for the i-th type 2 query.
Sample Input 1
6
1 0
1 1
1 0
2 2 3
1 2
2 0 5
Sample Output 1
1
5
Initially, A=(0).
- 1st query: Insert 1 immediately after 0. A becomes (0,1).
- 2nd query: Insert 2 immediately after 1. A becomes (0,1,2).
- 3rd query: Insert 3 immediately after 0. A becomes (0,3,1,2).
- 4th query: Remove the elements between 2 and 3, namely 1, and output the sum of the removed values, which is 1. A becomes (0,3,2).
- 5th query: Insert 5 immediately after 2. A becomes (0,3,2,5).
- 6th query: Remove the elements between 0 and 5, namely 3,2, and output the sum of the removed values, which is 5. A becomes (0,5).
Sample Input 2
2
1 0
2 0 1
Sample Output 2
0
In the 2nd query, we remove all elements between 0 and 1, but there are actually no such elements, so no elements are removed and the output value is 0.
Sample Input 3
10
1 0
1 1
2 0 2
2 0 2
1 0
1 5
2 0 5
2 2 6
1 6
1 9
Sample Output 3
1
0
0
0